

Kontext Data Lake combines uploaded files, managed Internal Iceberg storage, and project-level catalog access. Current support on this page reflects file ingestion and lakehouse capabilities in the current runtime.
Capabilities
| Capability | Support |
|---|---|
| Internal catalog | Internal Iceberg |
| External catalogs / databases | See Connect a data source |
| Execution modes | duckdb_federated, native_pushdown, materialized |
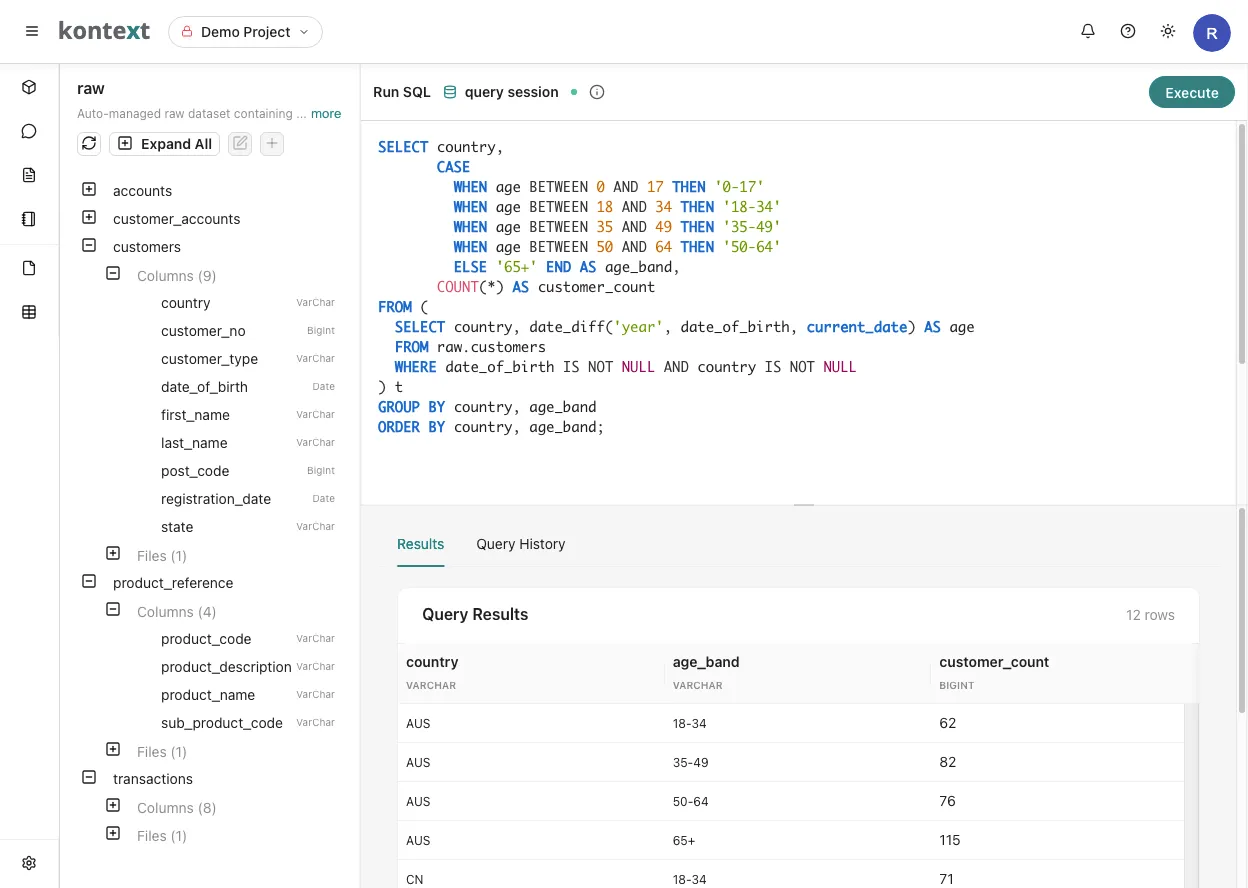
| Query surface | SQL editor, catalog browser, notebooks, AI-assisted workflows |
| Isolation model | Project-scoped storage, roles, and query context |
Uploaded files are profiled automatically and added to the project lakehouse context. Supported upload formats and connection providers are documented in the Kontext Studio user guide: Browse and manage files and Connect a data source.
Available In
| Surface | Usage |
|---|---|
| SQL editor | Query uploaded files and lakehouse-backed tables |
| Catalog browser | Browse the Internal Iceberg catalog and connected metadata |
| Notebooks | Use lakehouse data in project-scoped notebook analysis |
| Data agents | Ground AI analysis in uploaded and lakehouse-managed data |